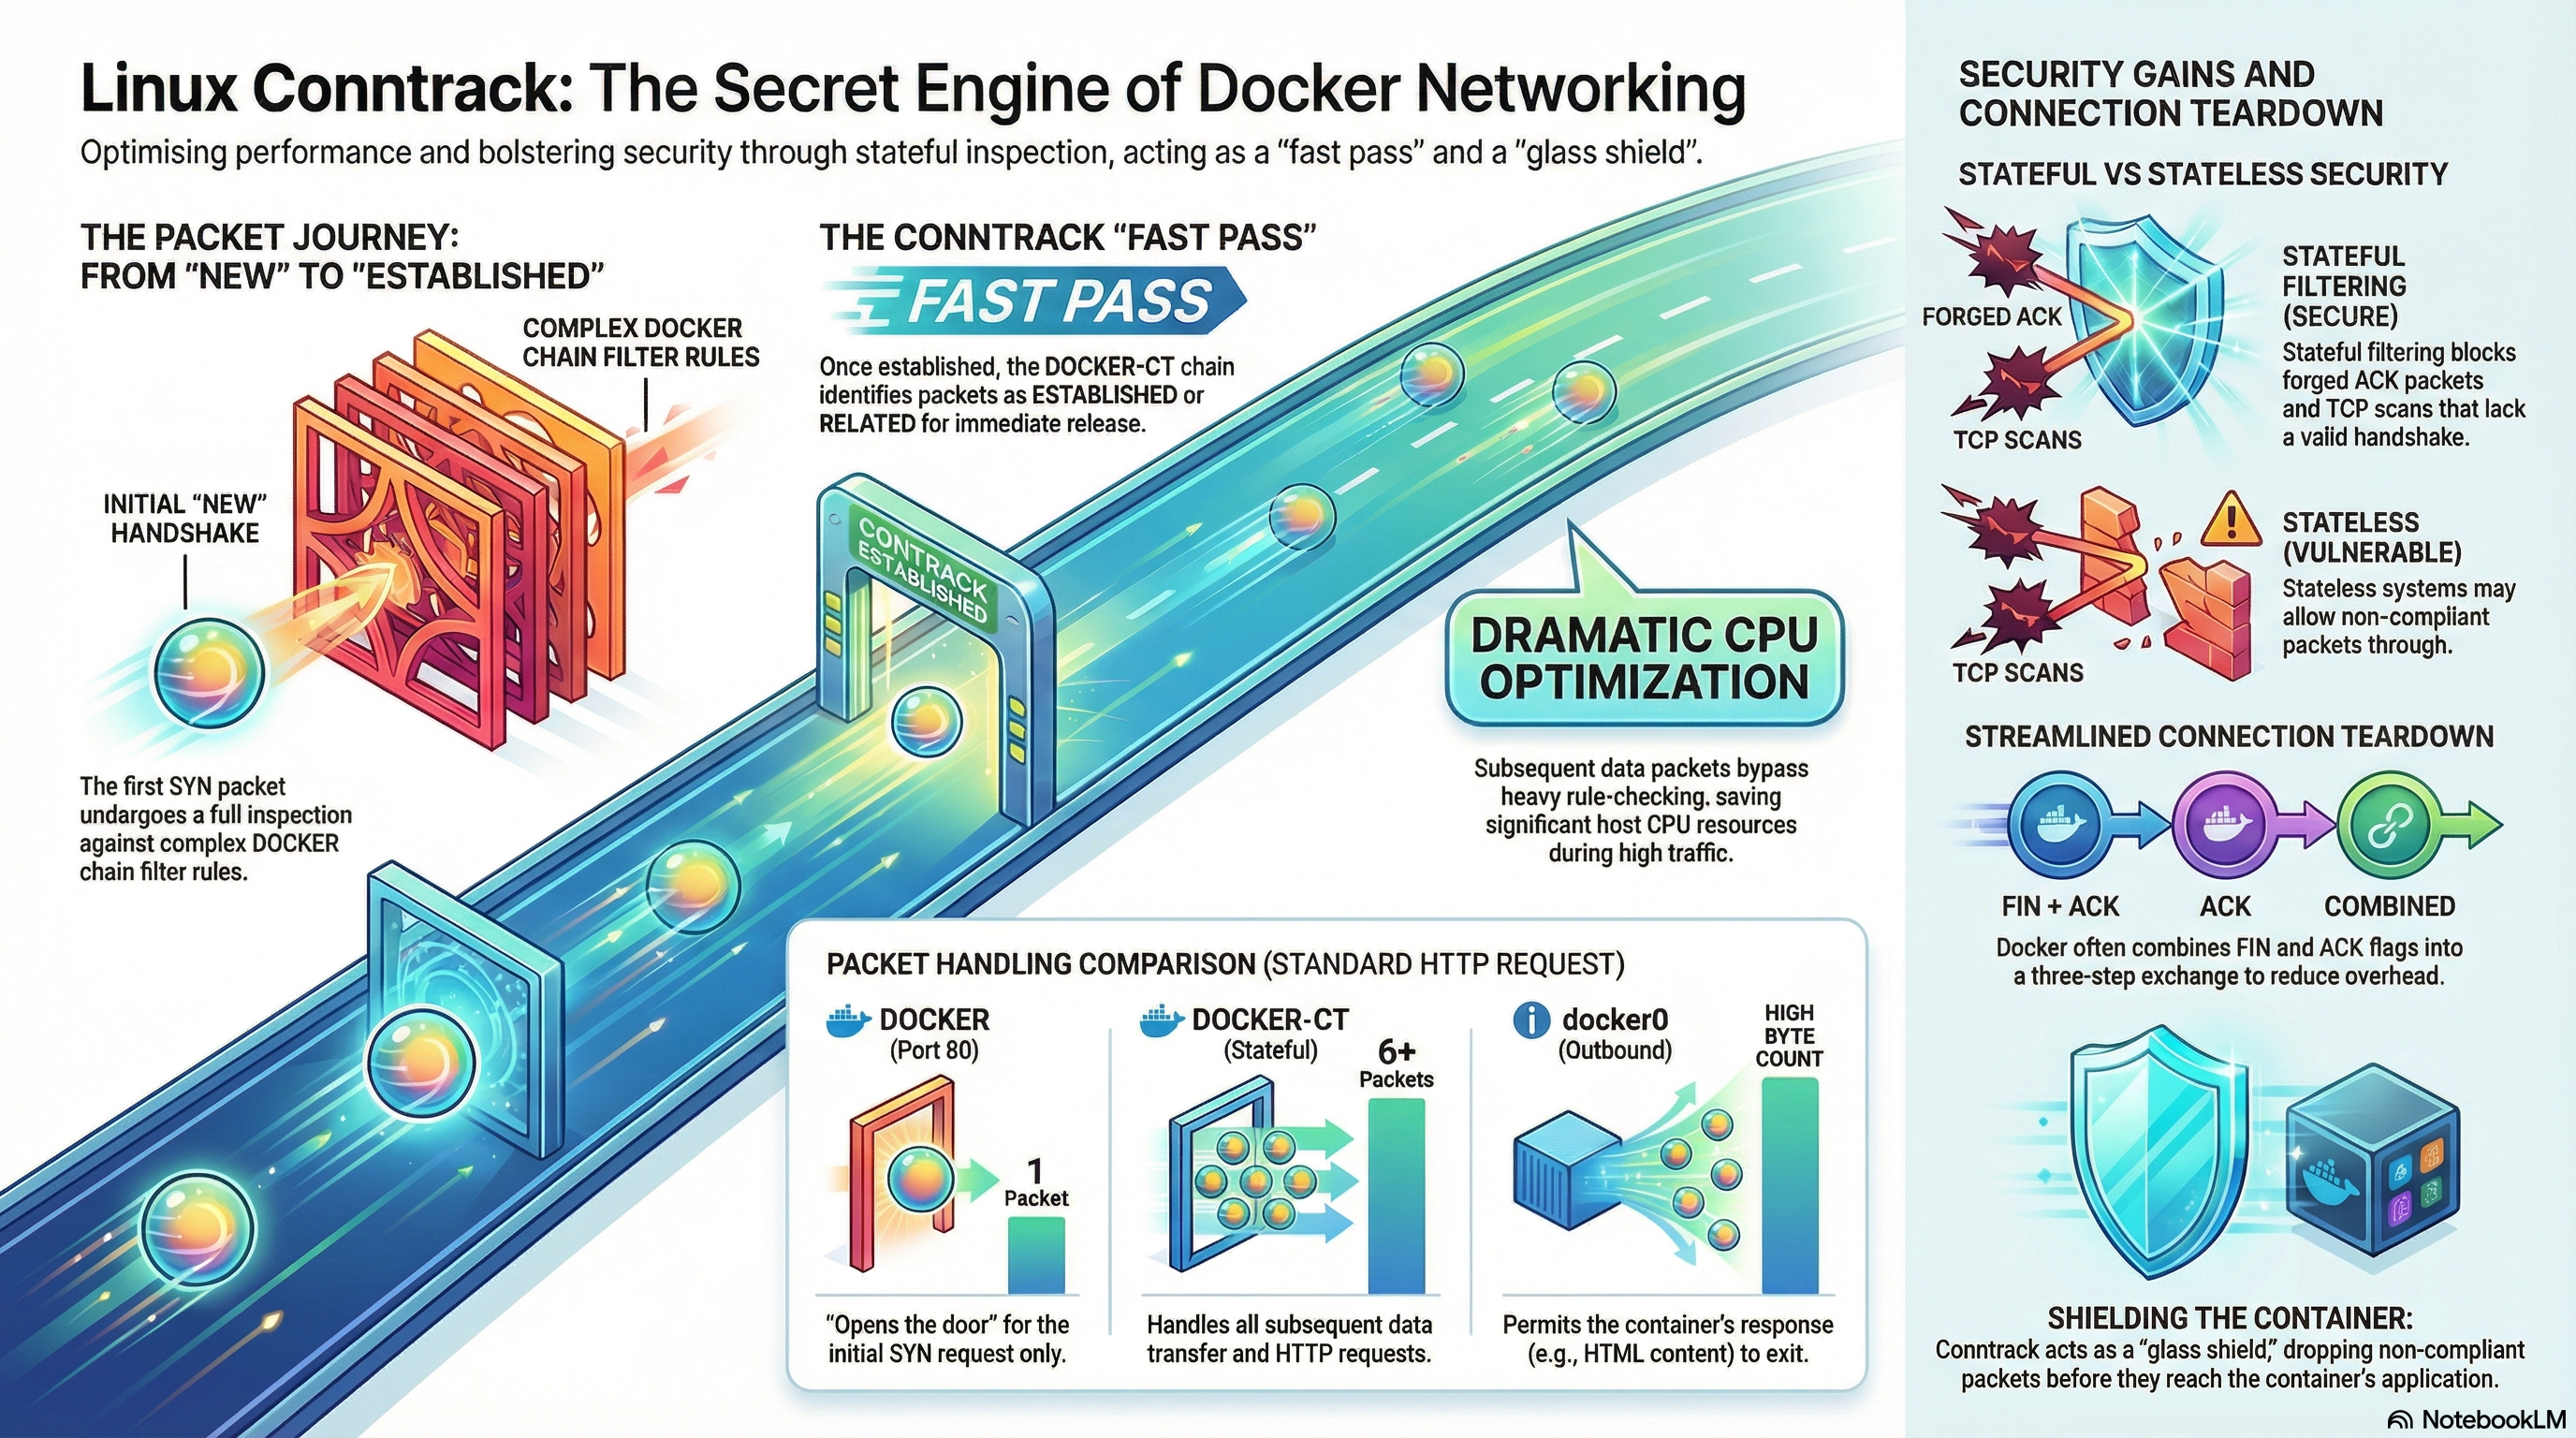
Why Your Kubernetes Services Are Latent: The Conntrack Table Ghost
This post is part of the Container Networking From Scratch series — follow a packet’s path through the Linux kernel, from namespaces to NAT.
Most engineers treat firewall rules like a simple list of IPs and ports. In reality, the Linux kernel is tracking every active connection in a finite memory structure called the conntrack table.
If you don’t understand how conntrack works, a traffic spike can silently break your cluster — with no useful application logs.
The Memory of the Linux Kernel
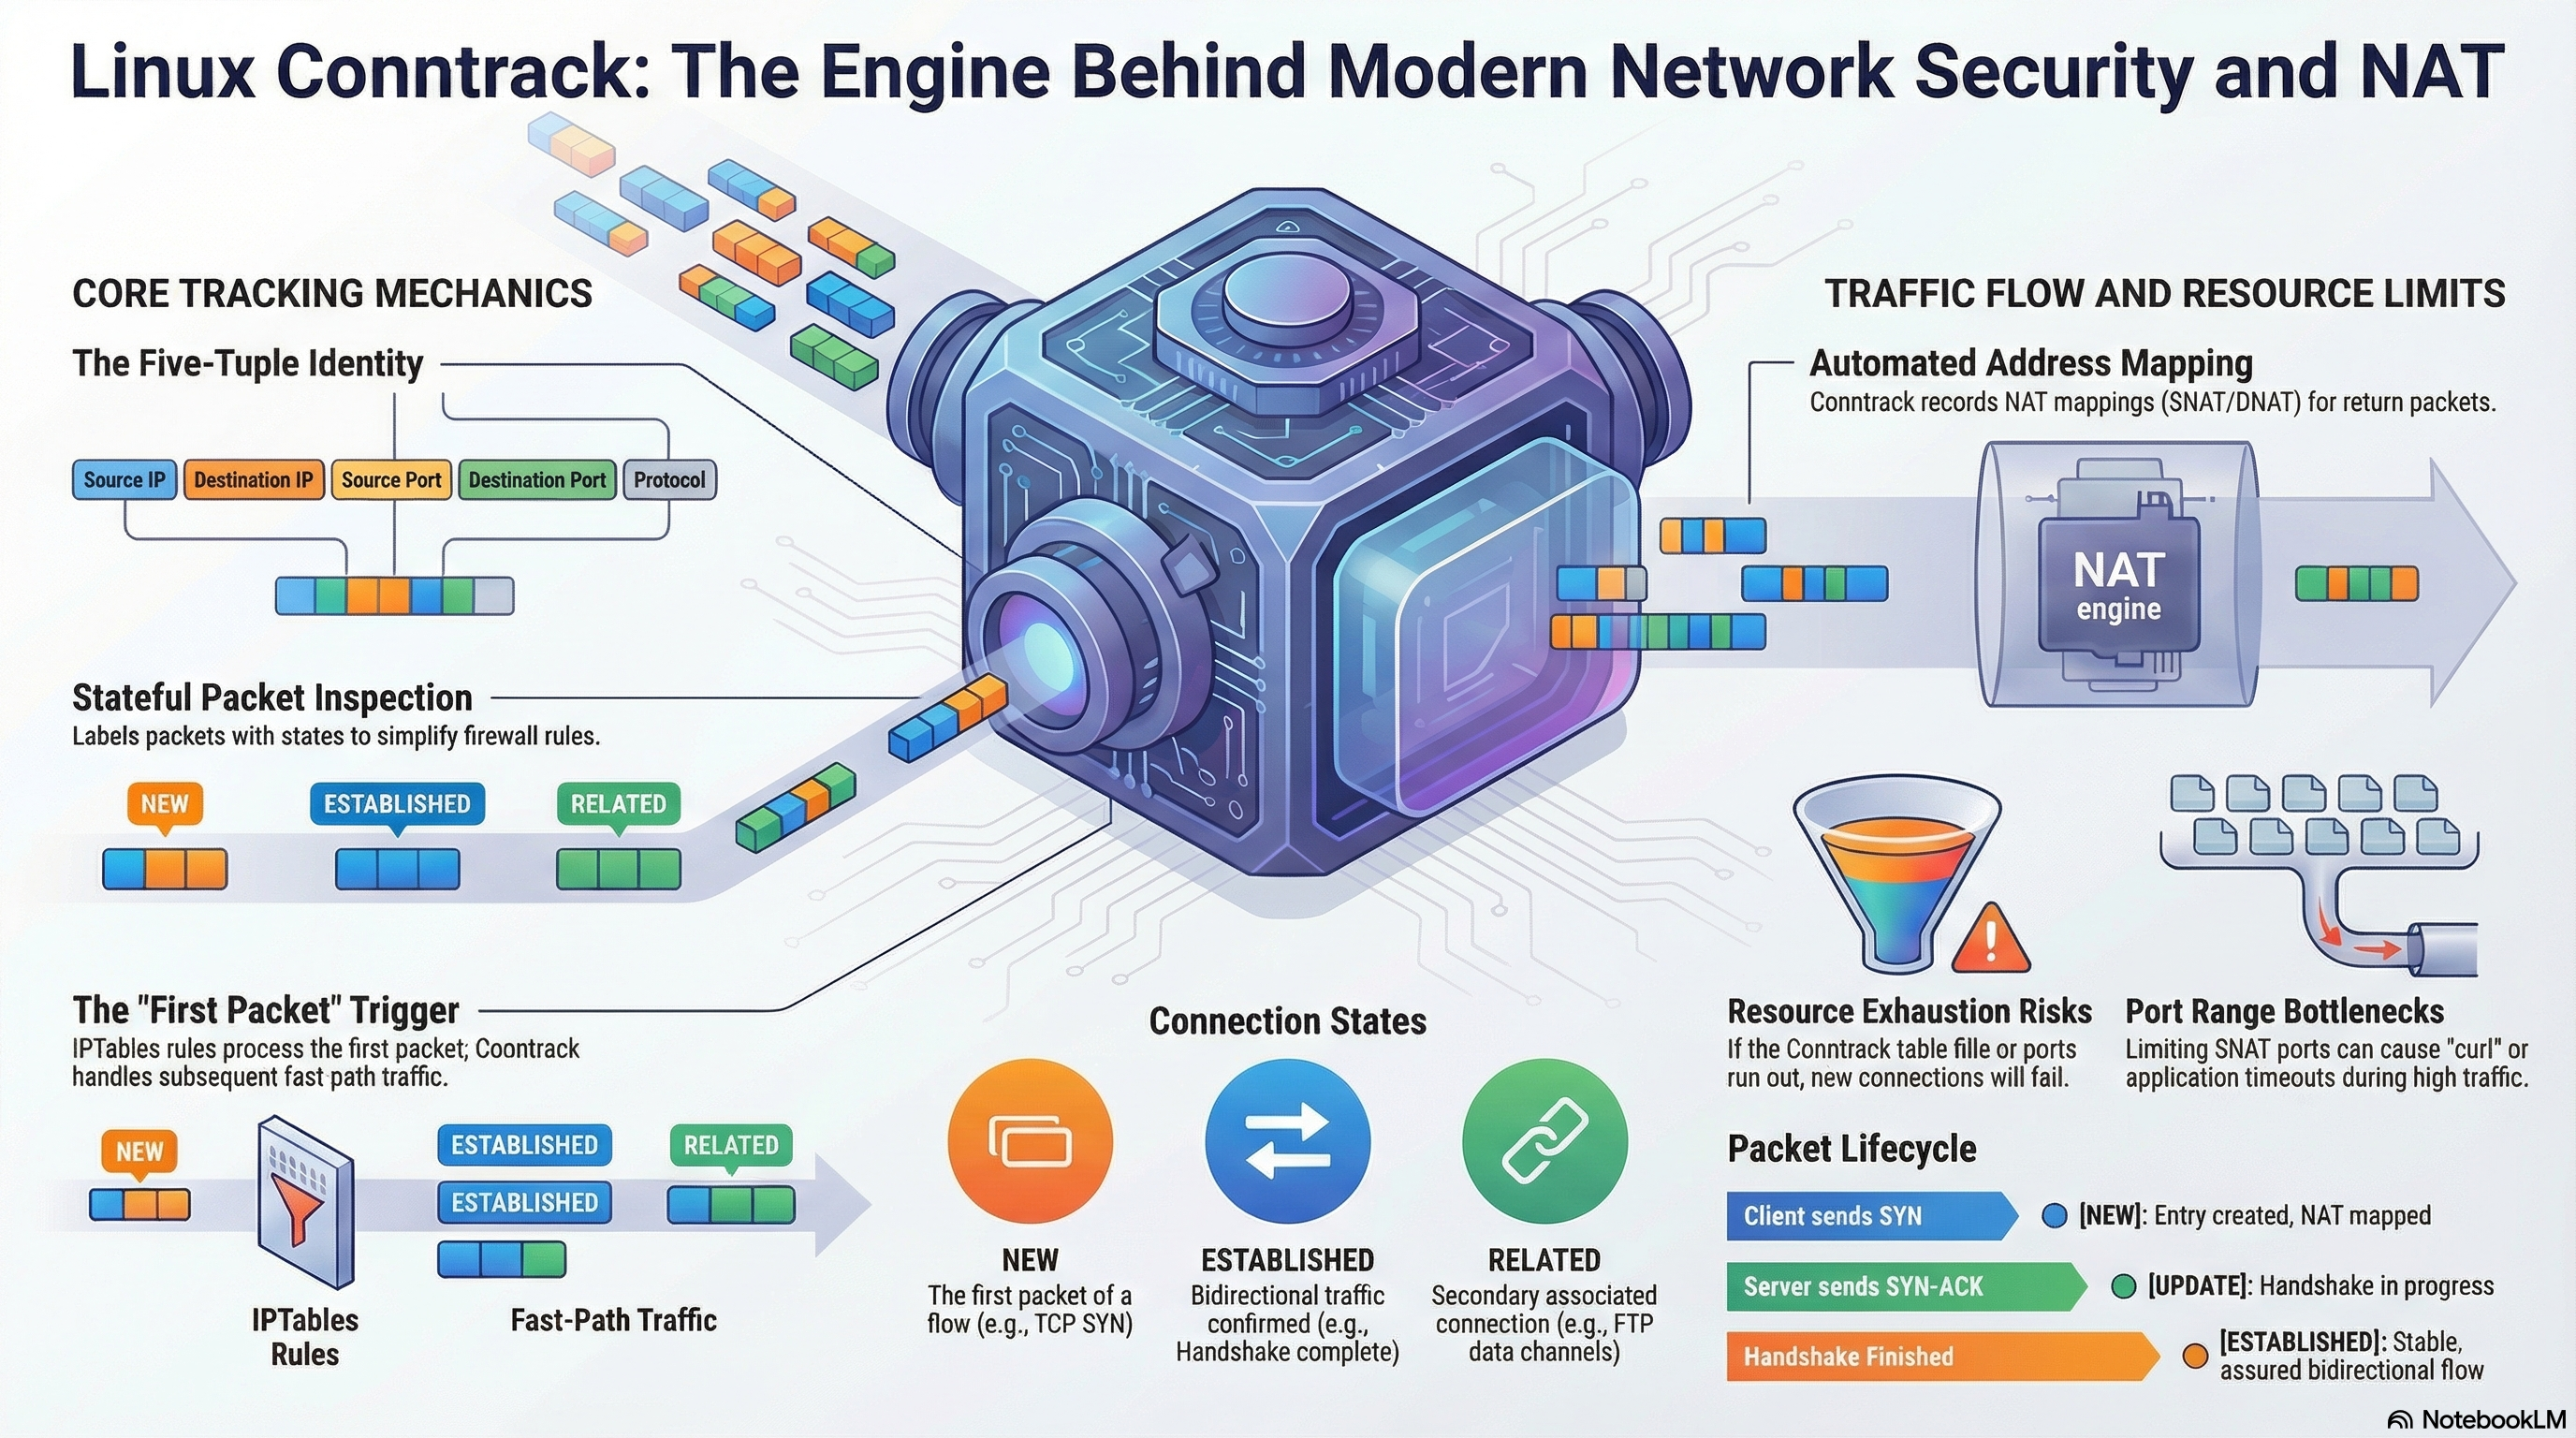
Modern container networking (Docker, Kubernetes, NAT) depends on Connection Tracking (Conntrack).
Conntrack is part of the Linux Netfilter framework. It tracks each connection using the five-tuple:
- Source IP
- Destination IP
- Source Port
- Destination Port
- Protocol
Without conntrack:
- NAT would not work
- Stateful firewalls would not exist
- Return traffic could not be matched correctly
Conntrack is essentially a kernel-level cache of active flows.
Lab Setup
We simulate load using two machines:
- Box-01 → Server (Docker + Nginx)
- Box-02 → Client (Ubuntu 24.04)
- Tools →
conntrack,iptables,ss,dmesg
Goal: observe connection states and push the conntrack table toward its limit.
Step 1: Watch Connections in Real Time
On Box-01:
$ sudo conntrack -E -p tcpExample output when a client connects:
    [NEW] tcp      6 120 SYN_SENT src=10.0.0.2 dst=10.0.0.1 sport=45232 dport=80
    [UPDATE] tcp   6 60 ESTABLISHED src=10.0.0.2 dst=10.0.0.1 sport=45232 dport=80
Explanation:
NEW→ first SYN packet seenESTABLISHED→ handshake completed- Kernel now fast-paths future packets
Step 2: Generate Traffic
On Box-02:
$ curl http://10.0.0.1Output:
<html>
<head><title>Welcome to nginx!</title></head>
<body>
<h1>Success</h1>
</body>
</html>
On Box-01, the connection lifecycle becomes visible.
Step 3: Inspect Current Conntrack Usage
Check current number of tracked entries:
$ cat /proc/sys/net/netfilter/nf_conntrack_countExample output:
1024Check the maximum allowed:
$ cat /proc/sys/net/netfilter/nf_conntrack_maxExample:
262144This means your kernel can only track 262,144 simultaneous connections.
Connection Lifecycle Breakdown
A TCP connection goes through these states:
- NEW
- ESTABLISHED
- FIN_WAIT
- TIME_WAIT
To see TIME_WAIT sockets:
$ ss -tan state time-wait | wc -lExample output:
18342These entries remain for up to 120 seconds by default.
That is the hidden problem.
The Invisible Wall: Table Full
When the conntrack table fills up, the kernel drops packets.
Check kernel logs:
$ dmesg | grep conntrackExample output:
nf_conntrack: table full, dropping packetAt this moment:
- Applications look healthy
- CPU looks normal
- Memory looks fine
- But new connections fail
The kernel silently discards packets because it cannot allocate a new conntrack entry.
The Important Firewall Rule
Most production firewalls begin with:
$ sudo iptables -A INPUT -m conntrack --ctstate ESTABLISHED,RELATED -j ACCEPTWhy this matters:
- Conntrack lookup = hash table (fast)
- Iptables rules = linear list (slow)
Once a connection is ESTABLISHED, packets skip most rule processing.
This improves performance significantly.
Real Production Scenario: Microservice Explosion
Imagine:
- Service opens a new TCP connection for every DB query
- Traffic spikes to 50,000 connections/sec
- Each connection stays in TIME_WAIT for 120 seconds
Within 1 minute:
- 3 million connection attempts
- Conntrack table max = 262,144
- Table fills
- Entire cluster appears “network unstable”
This is not a Kubernetes issue. This is state exhaustion.
Optimization Techniques
1. Reduce TIME_WAIT Duration
$ sudo sysctl -w net.netfilter.nf_conntrack_tcp_timeout_time_wait=30Verify:
$ sysctl net.netfilter.nf_conntrack_tcp_timeout_time_waitOutput:
net.netfilter.nf_conntrack_tcp_timeout_time_wait = 30Lower timeout = faster cleanup.
2. Increase Conntrack Limit Carefully
$ sudo sysctl -w net.netfilter.nf_conntrack_max=524288Be careful:
- Each entry consumes unswappable kernel memory
- Too high = risk during DDoS
3. Use NOTRACK for Stateless Traffic
For high-volume traffic that does not need tracking:
$ sudo iptables -t raw -A PREROUTING -p udp --dport 53 -j NOTRACKThis prevents DNS traffic from consuming conntrack entries.
Monitoring Strategy
Always monitor:
$ cat /proc/sys/net/netfilter/nf_conntrack_count
$ cat /proc/sys/net/netfilter/nf_conntrack_max
Alert when usage exceeds 80%.
In Kubernetes environments, export:
node_nf_conntrack_entriesnode_nf_conntrack_limit
Do not wait for drops to begin.
Mental Model: The Club Guest List
Think of conntrack like a club guest list:
- NEW → Person shows ID
- ESTABLISHED → Name is on the list, free entry
- TIME_WAIT → Name kept briefly after leaving
- Table Full → Club at capacity, nobody new enters
Even if the club looks empty inside, if the list is full, entry stops.
Key Takeaways
- Conntrack enables NAT and stateful firewalls
- It stores active connections in finite memory
- TIME_WAIT entries consume table space
- When full, kernel drops packets silently
- Monitor usage before it reaches the limit
- Fix root causes (connection pooling) before increasing limits
Understanding conntrack is mandatory for debugging Kubernetes networking, Docker traffic, and production latency issues.
If your services become randomly “slow” during load tests, check conntrack before blaming Kubernetes.